Loay Mualem
Postdoc @ Stuttgart

Hi, I'm Loay Mualem

Postdoctoral Researcher Β· IMPRS-IS & University of Stuttgart

I am currently a postdoctoral researcher at IMPRS-IS and the University of Stuttgart, working with Prof. Mathias Niepert at the Machine Learning and Simulation Lab (MLS Lab). I completed my Ph.D. in Computer Science at the University of Haifa, under the supervision of Prof. Moran Feldman and Prof. Dan Feldman.

My main research interests are Optimization, Machine/Deep Learning, and Big Data. I am passionate about employing provable optimization techniques to enhance the quality and accelerate the training of real-world Machine/Deep Learning models.

β–Ύ

01Experience

IMPRS-IS University of Stuttgart

IMPRS-IS + University of Stuttgart

Postdoctoral Researcher

October 2025 β€” Present

DataHeroes

DataHeroes

Lead DL + LLM Researcher

April 2023 β€” August 2025

University of Haifa

University of Haifa

M.Sc. + Ph.D. in Computer Science

Mar 2018 β€” Mar 2021 Β· Oct 2021 β€” Aug 2025

02Teaching @ University of Haifa

  • 2022–2024 Lecturer, Introduction to Computer Science
  • 2022–2024 B.Sc. final projects supervisor and mentor
  • 2021–2023 Lecturer, Introduction to Mathematics for first-year students
  • 2017–2021 Head TA, Introduction to Algorithms
  • 2016–2017, 2021–2022 Head TA, Data Structures
  • 2018–2021 Head TA, Introduction to Compilers

03Research

Preprints
Preprint

Improving Model Classification by Optimizing the Training Dataset

In the era of data-centric AI, the ability to curate high-quality training data is as crucial as model design. Coresets offer a principled approach to data reduction, enabling efficient learning on large datasets through importance sampling. However, conventional sensitivity-based coreset construction often falls short in optimizing for classification performance metrics, e.g., F 1 score, focusing instead on loss approximation. In this work, we present a systematic framework for tuning the coreset generation process to enhance downstream classification quality. Our method introduces new tunable parameters including deterministic sampling, class-wise allocation, and refinement via active sampling, beyond traditional sensitivity scores. Through extensive experiments on diverse datasets and classifiers, we demonstrate that tuned coresets can significantly outperform both vanilla coresets and full dataset training on key classification metrics, offering an effective path towards better and more efficient model training.

Submitted Papers
AXON

Supportive Token Revealing for Fast Diffusion Language Model Decoding

Giries Abu Ayoub, Mario Barbara, LluΓ­s Pastor-PΓ©rez, Tanja Bien, Aneesh Barthakur, Alaa Maalouf, Loay Mualem

Discrete diffusion language models can generate text efficiently by updating multiple masked positions in parallel, but this parallelism introduces a quality-latency trade-off. Aggressive decoding may commit mutually dependent tokens too early, while conservative decoding requires many denoising steps. Existing methods address this tension by deciding which tokens are safe to reveal using confidence or dependency criteria. However, avoiding unsafe commits does not necessarily make the remaining masked sequence easy to decode, since uncertain tokens may depend on masked tokens, creating a bottleneck for denoising steps. We propose AXON, a training-free module that can be added on top of existing parallel decoding strategies for diffusion language models. Rather than replacing the base decoder, AXON monitors the remaining uncertain masked tokens and intervenes only when their current state suggests that additional context is needed. It then shifts the criterion from which tokens are safest to reveal to which confident reveals would best support later denoising. AXON selects anchors, confident masked tokens that uncertain positions attend to, using attention, uncertainty, and confidence signals. Experiments on reasoning and code-generation benchmarks across multiple diffusion language models show that AXON improves the quality-latency trade-off of existing parallel decoders, often reducing the number of function evaluations while maintaining or improving accuracy.

SymDrift

SymDrift: One-Shot Generative Modeling under Symmetries

Samir Darouich, Vinh Tong, LluΓ­s Pastor-PΓ©rez, Tanja Bien, Loay Mualem, Mathias Niepert

Generative modeling of physical systems, such as molecules, requires learning distributions that are invariant under global symmetries, such as rotations in three-dimensional space. Equivariant diffusion and flow matching models can incorporate such invariances effectively, even when trained on a non-invariant empirical distribution, but they typically rely on costly multi-step sampling. Recently, drifting models have emerged as an efficient alternative, enabling single-step generation and achieving state-of-the-art performance in generative modeling tasks. However, we show that drifting models face a symmetry-specific challenge, since an equivariant generator does not generally produce the same drifting field as the one obtained from the symmetrized target distribution. Addressing this issue would require expensive symmetrization of the empirical distribution. To avoid this cost, we propose SymDrift, a framework that makes the drifting field itself symmetry-aware. We introduce two complementary strategies: (i) a symmetrized drift in coordinate space based on optimal alignment, and (ii) a G-invariant embedding that removes symmetry ambiguity by construction. Empirically, SymDrift outperforms existing one-shot methods on standard benchmarks for conformer and transition state generation, while remaining competitive with significantly more expensive multi-step approaches. By enabling one-shot inference, SymDrift reduces computational overhead by up to 40Γ— compared to existing baselines, making it promising for high-throughput applications such as virtual drug screening and large-scale reaction network exploration.

ARIA

ARIA: Adaptive Region-Based Importance Allocation for Conditional Diffusion Distillation

Loay Mualem, Vinh Tong, Samir Darouich, Mathias Niepert

Conditional diffusion distillation seeks to transfer a large teacher model to a smaller student while preserving alignment with conditioning inputs, but generalization is often difficult when the conditioning space is broad and training data is limited. In practice, only a restricted synthetic dataset is typically available while possible conditions (such as text prompts) are much larger, which makes uniform training inefficient. ARIA studies this challenge under realistic training budgets and evaluates performance across multiple student architectures. Experiments show consistent FID improvements, including up to 10% relative gains in unseen regimes and up to 40% faster convergence.

SpurAudio illustration

SpurAudio: A Benchmark for Studying Shortcut Learning in Few-Shot Audio Classification

Giries Abu Ayoub, Morad Tukan, Loay Mualem

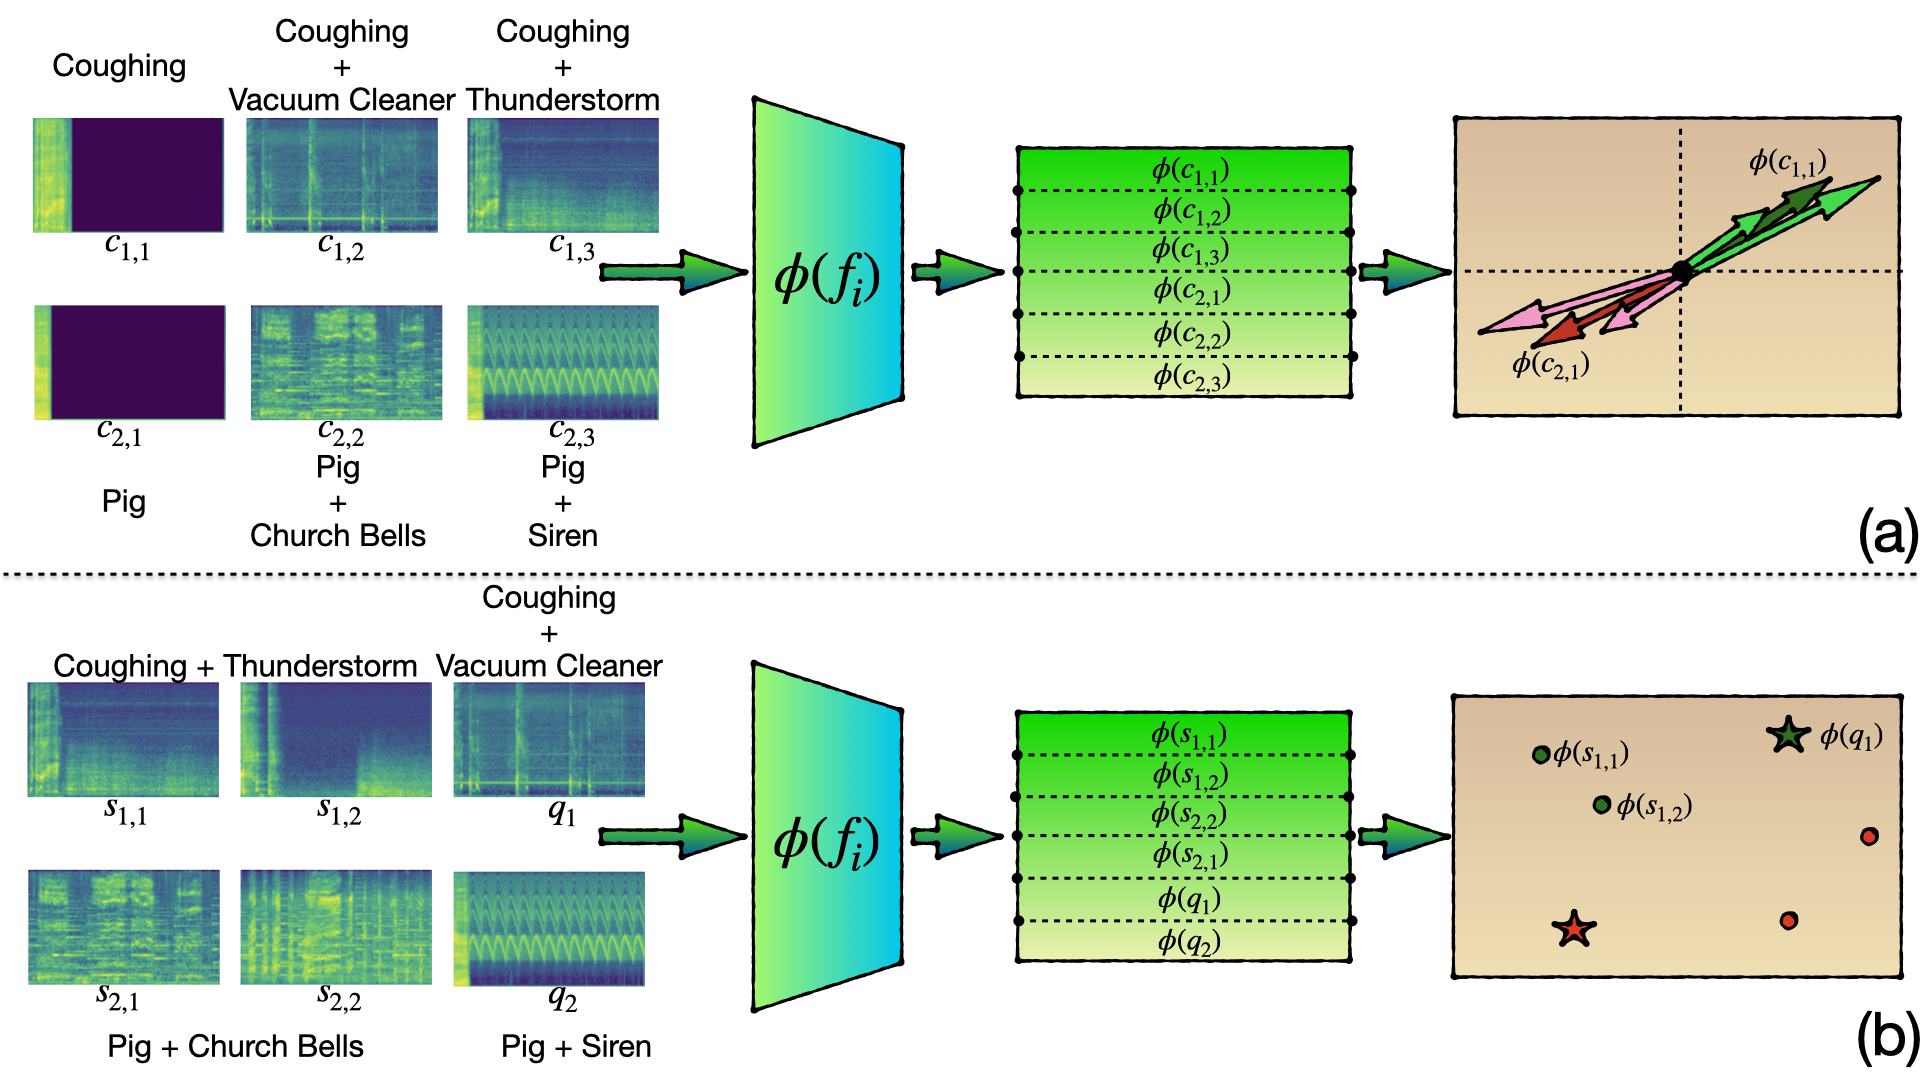
Few-shot classification (FSC) is widely used for learning from limited labeled data, yet most evaluations implicitly assume that target concepts are independent of contextual cues. In real-world settings, however, examples often appear within rich contexts, allowing models to exploit spurious correlations between foreground content and background signals. While such effects have been studied in few-shot image classification, their role in few-shot audio classification remains largely unexplored, and existing audio benchmarks offer limited control over contextual structure. We introduce SpurAudio, a benchmark that leverages the natural separability of foreground events and background environments in audio to enable controlled, multi-level evaluation of contextual shifts across support and query sets. Using this benchmark, we show that many state-of-the-art few-shot methods suffer severe performance degradation when background correlations are disrupted, despite achieving similar accuracy under standard evaluation protocols. Moreover, methods that appear comparable under conventional benchmarks can exhibit markedly different sensitivity to spurious correlations, as few-shot performance is shaped by how well feature representations align with classifier heads, revealing systematic algorithmic strengths and vulnerabilities. These findings provide new insight into the behavior of few-shot methods in audio and highlight the need for benchmarks that explicitly probe context dependence when evaluating FSC models.

ORB-SLAM3 drones

ORBSLAM3-Enhanced Autonomous Toy Drones: Pioneering Indoor Exploration

Murad Tukan, Fares Fares, Yotam Grufinkle, Ido Talmor, Loay Mualem, Vladimir Braverman, Dan Feldman

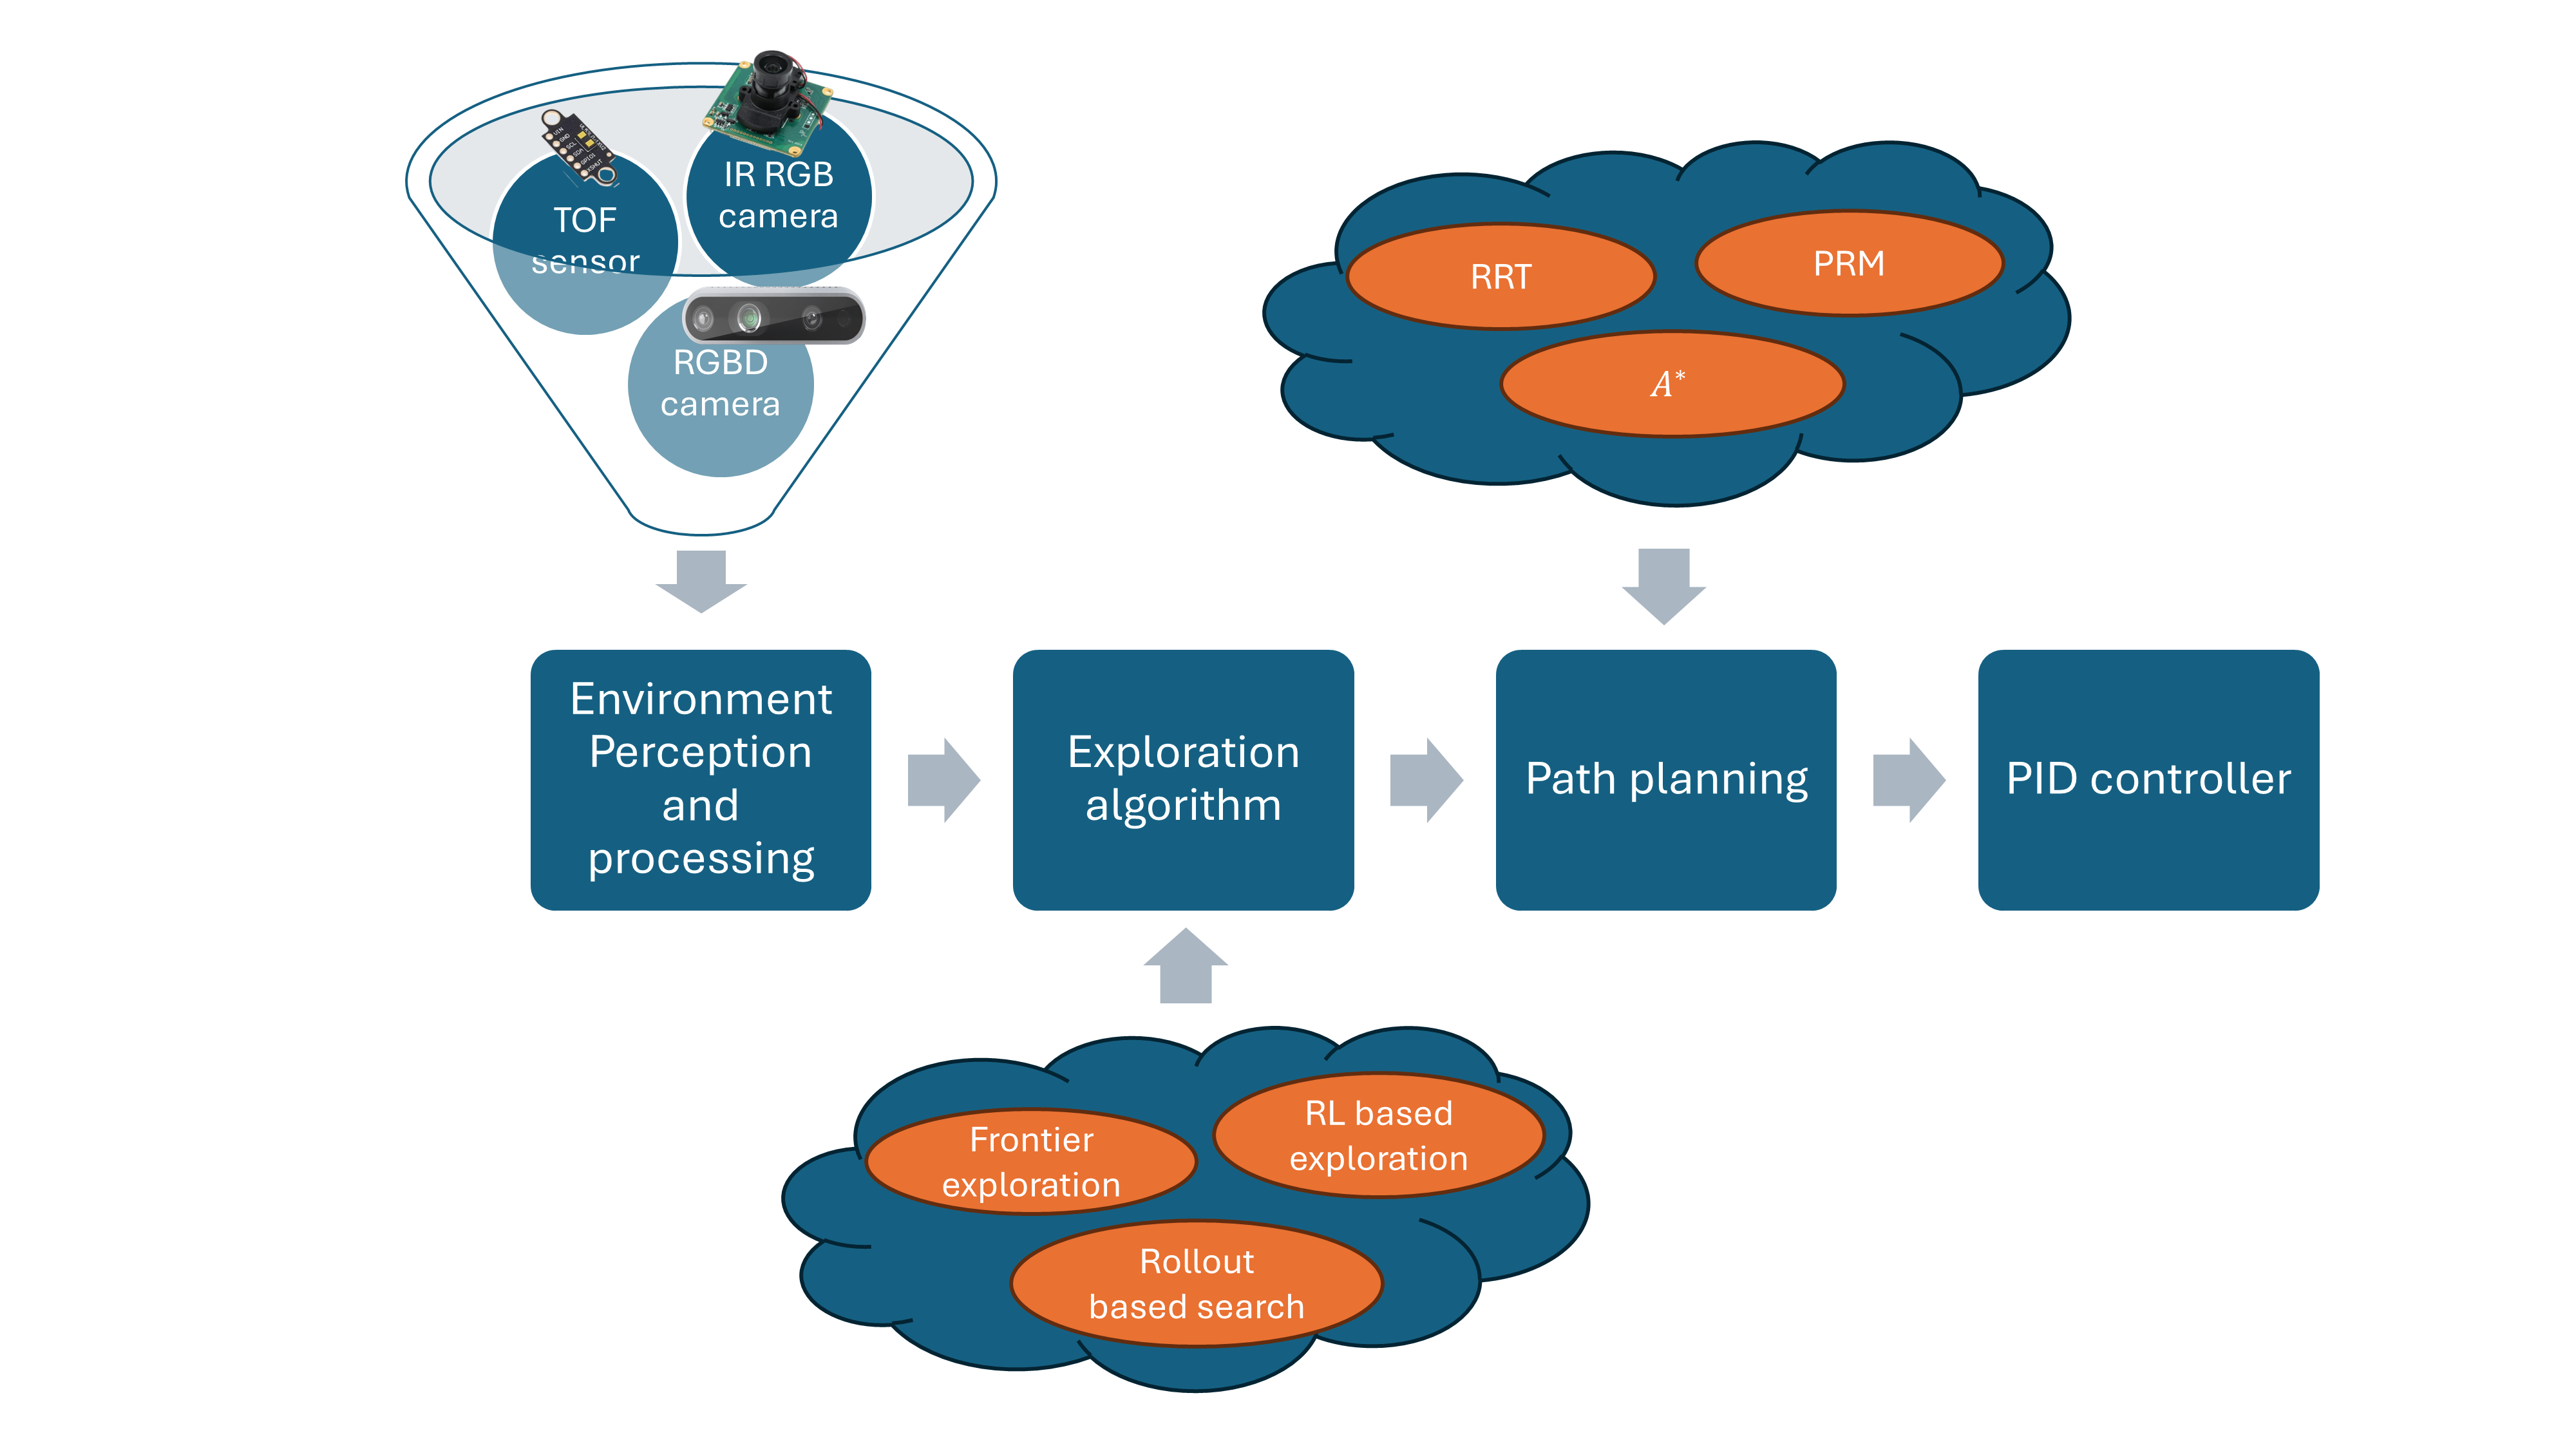
Navigating toy drones through uncharted GPS-denied indoor spaces poses significant difficulties due to their reliance on GPS for location determination. In such circumstances, the necessity for achieving proper navigation is a primary concern. In response to this formidable challenge, we introduce a real-time autonomous indoor exploration system tailored for drones equipped with a monocular RGB camera. Our system utilizes ORB-SLAM3, a state-of-the-art vision feature-based SLAM, to handle both the localization of toy drones and the mapping of unmapped indoor terrains. Aside from the practicability of ORB-SLAM3, the generated maps are represented as sparse point clouds, making them prone to the presence of outlier data. To address this challenge, we propose an outlier removal algorithm with provable guarantees. Furthermore, our system incorporates a novel exit detection algorithm, ensuring continuous exploration by the toy drone throughout the unfamiliar indoor environment. We also transform the sparse point to ensure proper path planning using existing path planners. To validate the efficacy and efficiency of our proposed system, we conducted offline and real-time experiments on the autonomous exploration of indoor spaces. The results from these endeavors demonstrate the effectiveness of our methods.

@article{tukan2023orbslam3,
  title={Orbslam3-enhanced autonomous toy drones: Pioneering indoor exploration},
  author={Tukan, Murad and Fares, Fares and Grufinkle, Yotam and Talmor, Ido and Mualem, Loay and Braverman, Vladimir and Feldman, Dan},
  journal={arXiv preprint arXiv:2312.13385},
  year={2023}
}
Publications
Practical 0.385-approximation

Practical 0.385-Approximation for Submodular Maximization Subject to a Cardinality Constraint

Murad Tukan, Loay Mualem, Moran Feldman

NeurIPS 2024

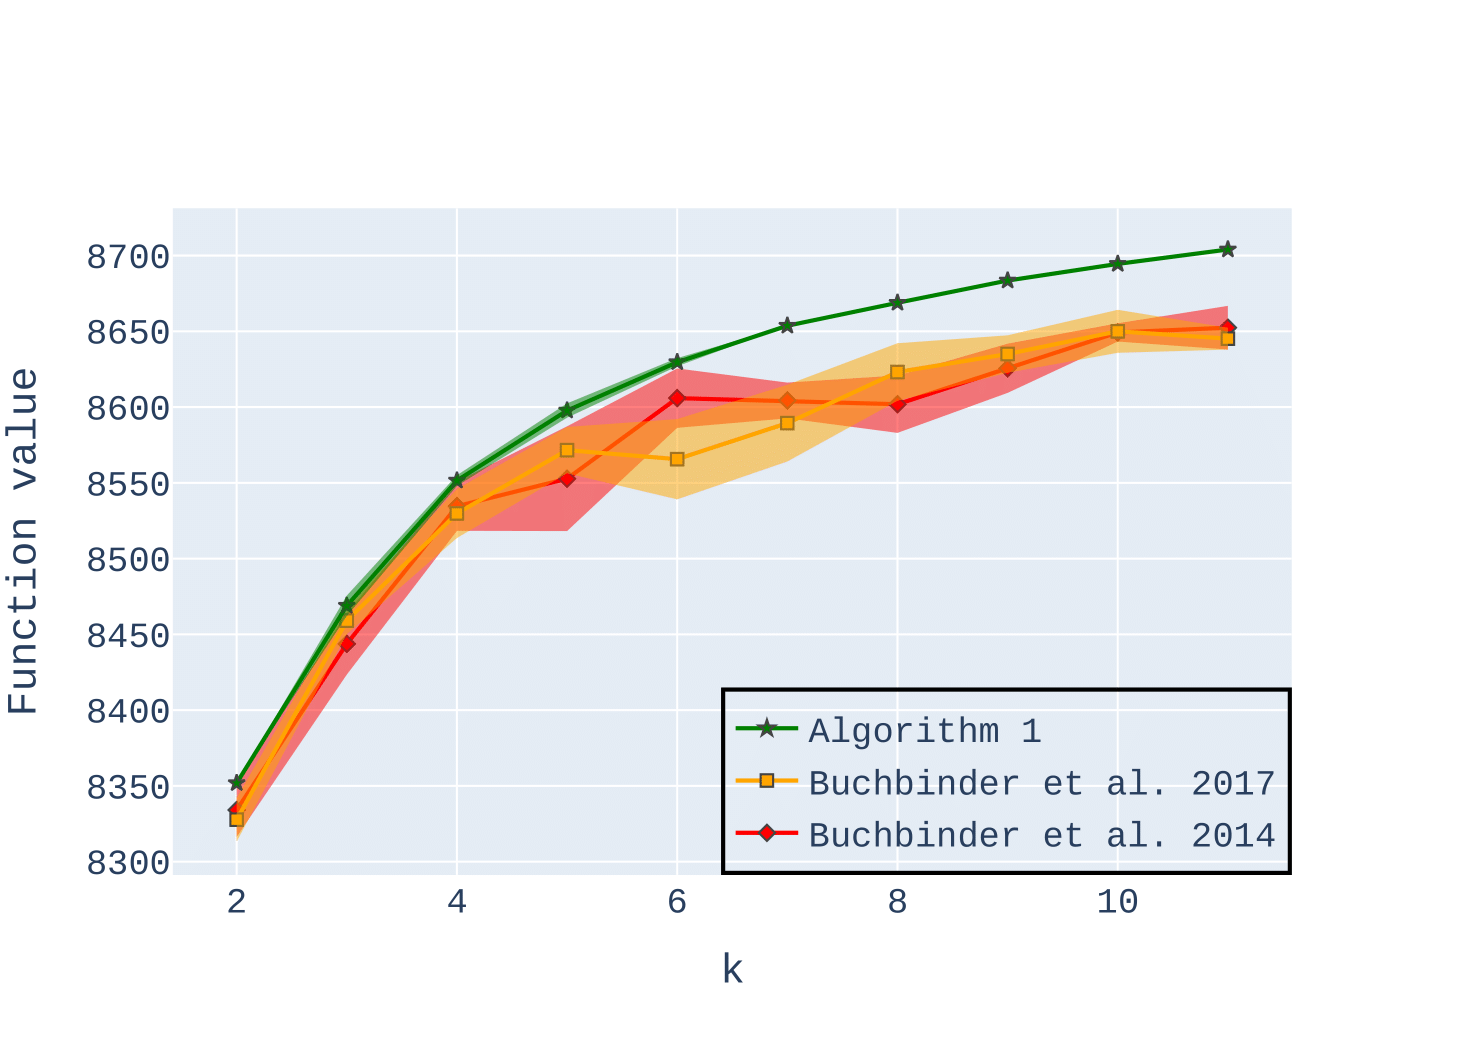
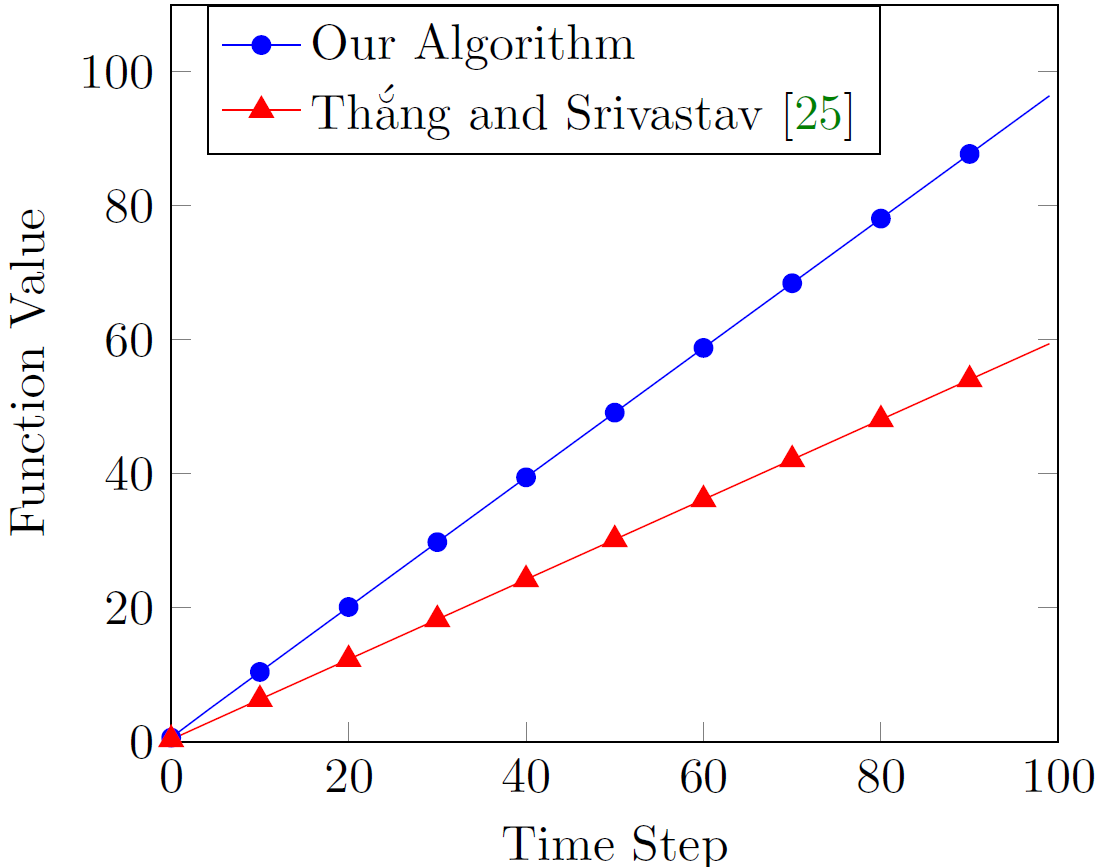
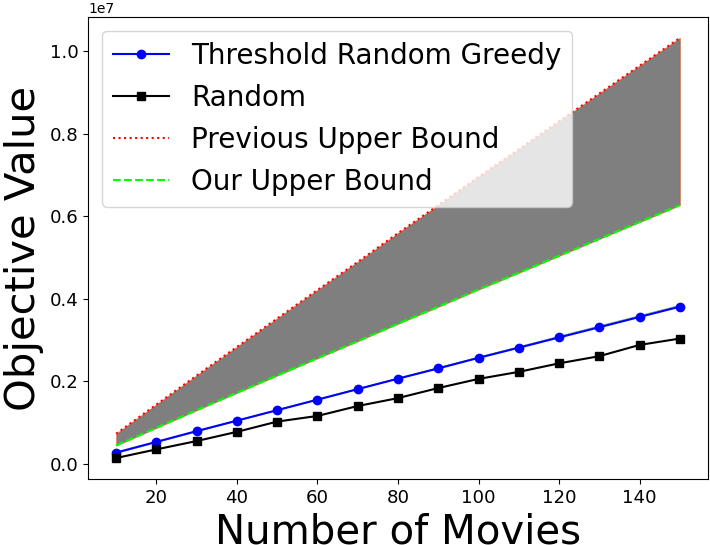
Non-monotone constrained submodular maximization plays a crucial role in various machine learning applications. However, existing algorithms often struggle with a trade-off between approximation guarantees and practical efficiency. The current state-of-the-art is a recent 0.401-approximation algorithm, but its computational complexity makes it highly impractical. The best practical algorithms for the problem only guarantee 1/e-approximation. In this work, we present a novel algorithm for submodular maximization subject to a cardinality constraint that combines a guarantee of 0.385-approximation with a low and practical query complexity of O(n+kΒ²). Furthermore, we evaluate the empirical performance of our algorithm in experiments based on various machine learning applications, including Movie Recommendation, Image Summarization, and more. These experiments demonstrate the efficacy of our approach.

@article{tukan2024practical,
  title={Practical $0.385$-Approximation for Submodular Maximization Subject to a Cardinality Constraint},
  author={Tukan, Murad and Mualem, Loay and Feldman, Moran},
  journal={Advances in Neural Information Processing Systems},
  volume={37},
  pages={51223--51253},
  year={2024}
}
Bridging the gap

Bridging the Gap Between General and Down-Closed Convex Sets in Submodular Maximization

Loay Mualem, Murad Tukan, Moran Feldman

IJCAI 2024

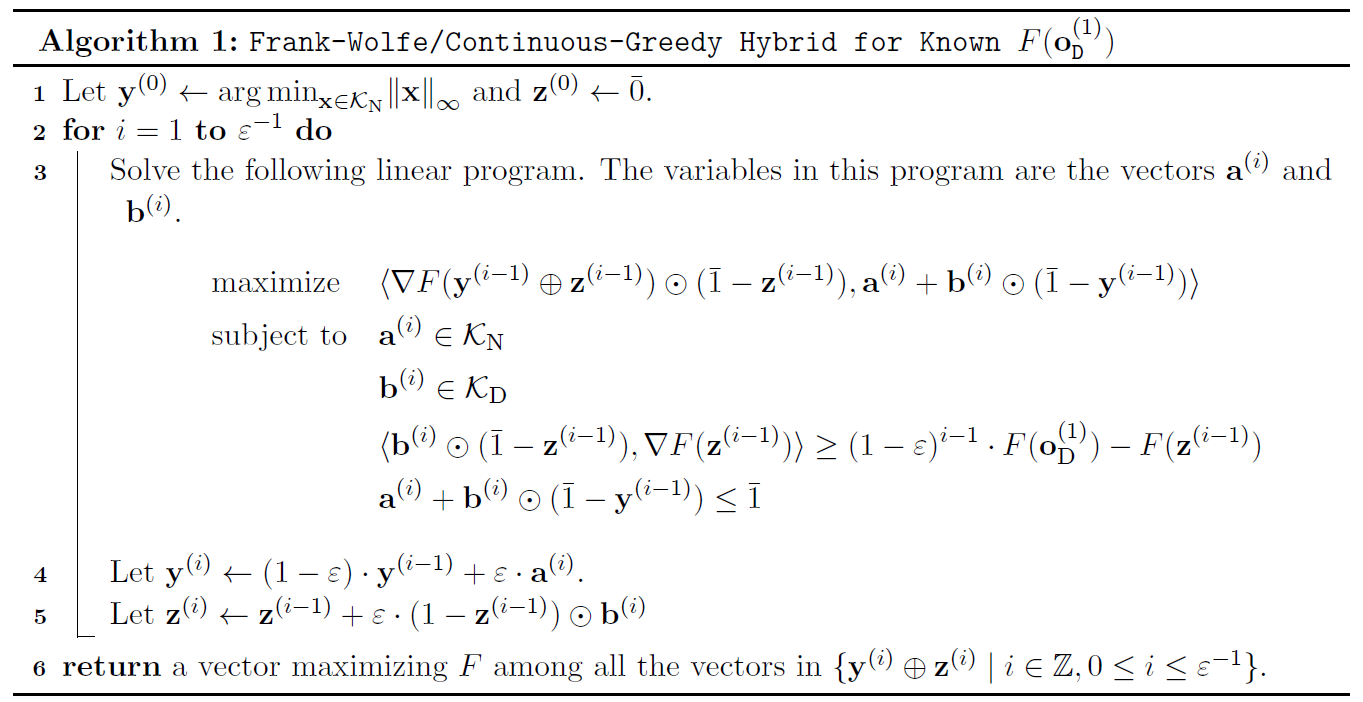
Optimization of DR-submodular functions has experienced a notable surge in significance in recent times, marking a pivotal development within the domain of non-convex optimization. Motivated by real-world scenarios, some recent works have delved into the maximization of non-monotone DR-submodular functions over general (not necessarily down-closed) convex set constraints. Up to this point, these works have all used the minimum L-infinity norm of any feasible solution as a parameter. Unfortunately, a recent hardness result due to Mualem and Feldman shows that this approach cannot yield a smooth interpolation between down-closed and non-down-closed constraints. In this work, we suggest novel offline and online algorithms that provably provide such an interpolation based on a natural decomposition of the convex body constraint into two distinct convex bodies: a down-closed convex body and a general convex body. We also empirically demonstrate the superiority of our proposed algorithms across three offline and two online applications.

@article{mualem2024bridging,
  title={Bridging the Gap Between General and Down-Closed Convex Sets in Submodular Maximization},
  author={Mualem, Loay and Tukan, Murad and Fledman, Moran},
  journal={arXiv preprint arXiv:2401.09251},
  year={2024}
}
Privacy preserving EPM

Privacy Preserving Epigenetic PaceMaker: Stronger Privacy and Improved Efficiency

Meir Goldenberg, Loay Mualem, Amit Shahar, Sagi Snir, Adi Akavia

Genome Research

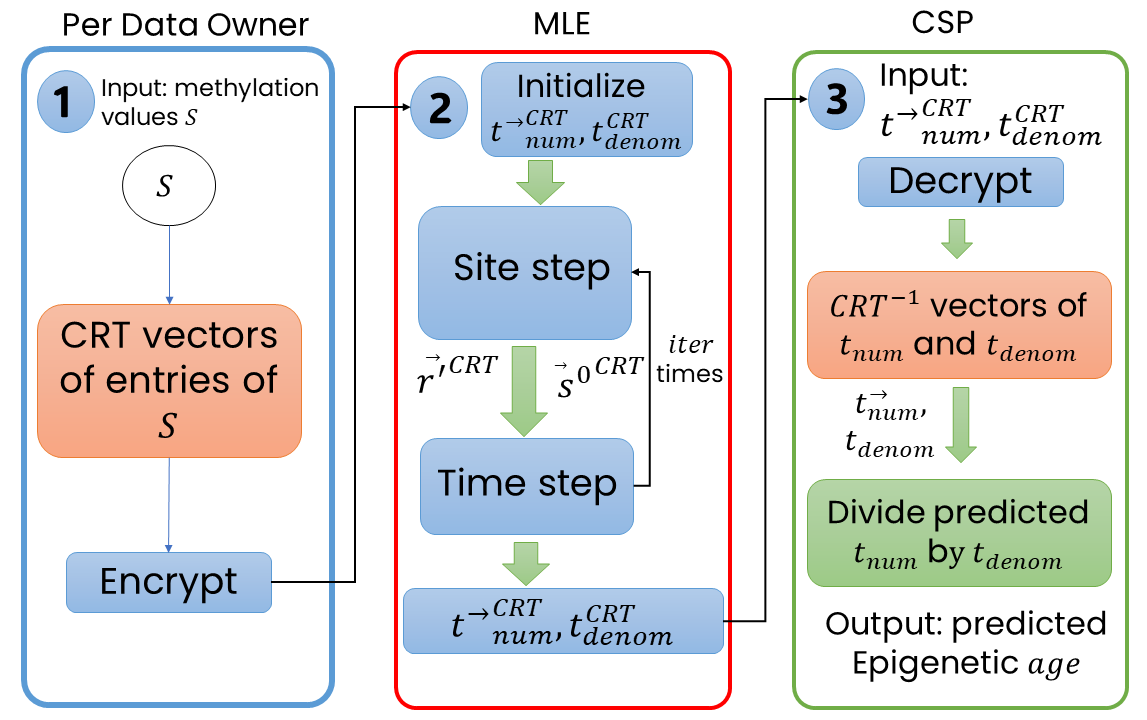
DNA methylation data plays a crucial role in estimating chronological age in mammals, offering real-time insights into an individual's aging process. The Epigenetic Pacemaker (EPM) model allows inference of the biological age as deviations from the population trend. Given the sensitivity of this data, it is essential to safeguard both inputs and outputs of the EPM model. In a recent study by Goldenberg et al., a privacy-preserving approach for EPM computation was introduced, utilizing Fully Homomorphic Encryption (FHE). However, their method had limitations, including having high communication complexity and being impractical for large datasets. Our work presents a new privacy preserving protocol for EPM computation, analytically improving both privacy and complexity. Notably, we employ a single server for the secure computation phase while ensuring privacy even in the event of server corruption (compared to requiring two non-colluding servers in Goldenberg et al). Using techniques from symbolic algebra and number theory, the new protocol eliminates the need for communication during secure computation, significantly improves asymptotic runtime and offers better compatibility to parallel computing for further time complexity reduction. We have implemented our protocol, demonstrating its ability to produce results similar to the standard (insecure) EPM model with substantial performance improvement compared to Goldenberg et al. These findings hold promise for enhancing data security in medical applications where personal privacy is paramount. The generality of both the new approach and the EPM, suggests that this protocol may be useful to other uses employing similar expectation maximization techniques.

@inproceedings{goldenberg2024privacy,
  title={Privacy Preserving Epigenetic PaceMaker: Stronger Privacy and Improved Efficiency},
  author={Goldenberg, Meir and Mualem, Loay and Shahar, Amit and Snir, Sagi and Akavia, Adi},
  booktitle={International Conference on Research in Computational Molecular Biology},
  pages={412--416},
  year={2024},
  organization={Springer}
}
Econeurobiology

Econeurobiology and Brain Development in Children: Key Factors Affecting Development, Behavioral Outcomes, and School Interventions

Raed Mualem, Leon Morales-Quezada, Rania Hussein Farraj, Shir Shance, Dana Hodaya Bernshtein, Sapir Cohen, Loay Mualem, Niven Salem, Rivka Riki Yehuda, Yusra Zbedat, and others

Frontiers in Public Health 2024

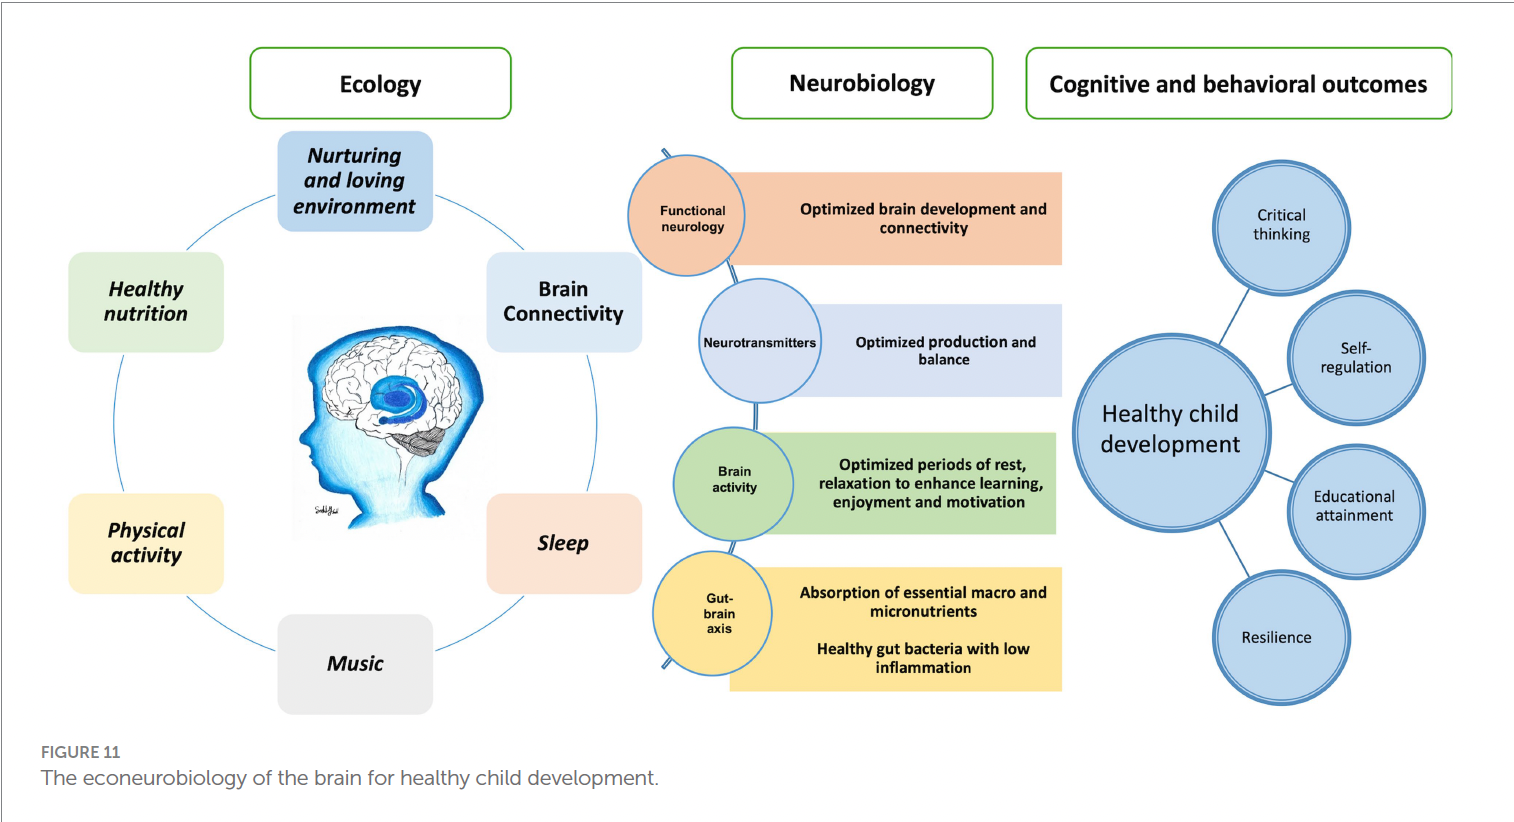
The Econeurobiology of the brain describes the environment in which an individual's brain develops. This paper explores the complex neural mechanisms that support and evaluate enrichment at various stages of development, providing an overview of how they contribute to plasticity and enhancement of both achievement and health. It explores the deep benefits of enrichment and contrasts them with the negative effects of trauma and stress on brain development. In addition, the paper strongly emphasizes the integration of Gardner's intelligence types into the school curriculum environment. It emphasizes the importance of linking various intelligence traits to educational strategies to ensure a holistic approach to cognitive development. In the field of Econeurobiology, this work explains the central role of the environment in shaping the development of the brain. It examines brain connections and plasticity and reveals the impact of certain environmental factors on brain development in early and mid-childhood. In particular, the six key factors highlighted are an environment of support, nutrition, physical activity, music, sleep, and cognitive strategies, highlighting their potential to improve cognitive abilities, memory, learning, self-regulation, and social and emotional development. This paper also investigates the social determinants of health and education in the context of Econeurobiology. It emphasizes the transformative power of education in society, especially in vulnerable communities facing global challenges in accessing quality education.

@article{mualem2024econeurobiology,
  title={Econeurobiology and brain development in children: key factors affecting development, behavioral outcomes, and school interventions},
  author={Mualem, Raed and Morales-Quezada, Leon and Farraj, Rania Hussein and Shance, Shir and Bernshtein, Dana Hodaya and Cohen, Sapir and Mualem, Loay and Salem, Niven and Yehuda, Rivka Riki and Zbedat, Yusra and others},
  journal={Frontiers in public health},
  volume={12},
  pages={1376075},
  year={2024},
  publisher={Frontiers Media SA}
}
Submodular minimax optimization

Submodular Minimax Optimization: Finding Effective Sets

Loay Mualem, Ethan R. Elenberg, Moran Feldman, Amin Karbasi

AISTATS 2024

Despite the rich existing literature about minimax optimization in continuous settings, only very partial results of this kind have been obtained for combinatorial settings. In this paper, we fill this gap by providing a characterization of submodular minimax optimization, the problem of finding a set (for either the min or the max player) that is effective against every possible response. We show when and under what conditions we can find such sets. We also demonstrate how minimax submodular optimization provides robust solutions for downstream machine learning applications such as (i) prompt engineering in large language models, (ii) identifying robust waiting locations for ride-sharing, (iii) kernelization of the difficulty of instances of the last setting, and (iv) finding adversarial images. Our experiments show that our proposed algorithms consistently outperform other baselines.

@inproceedings{mualem2024submodular,
  title={Submodular minimax optimization: Finding effective sets},
  author={Mualem, Loay Raed and Elenberg, Ethan R and Feldman, Moran and Karbasi, Amin},
  booktitle={International Conference on Artificial Intelligence and Statistics},
  pages={1081--1089},
  year={2024},
  organization={PMLR}
}
Resolving approximability

Resolving the Approximability of Offline and Online Non-monotone DR-Submodular Maximization over General Convex Sets

Loay Mualem, Moran Feldman

AISTATS 2023

In recent years, maximization of DR-submodular continuous functions became an important research field, with many real-world applications in the domains of machine learning, communication systems, operation research, and economics. Most of the works in this field study maximization subject to down-closed convex set constraints due to an inapproximability result. However, Durr et al. showed that one can bypass this inapproximability by proving approximation ratios that are functions of m, the minimum L-infinity-norm of any feasible vector. Given this observation, it is possible to get results for maximizing a DR-submodular function subject to general convex set constraints, which has led to multiple works on this problem. The most recent of which is a polynomial time 1/4(1 βˆ’ m)-approximation offline algorithm due to Du. However, only a sub-exponential time (1/3√3)(1 βˆ’ m)-approximation algorithm is known for the corresponding online problem. In this work, we present a polynomial time online algorithm matching the 1/4(1 βˆ’ m)-approximation of the state-of-the-art offline algorithm. We also present an inapproximability result showing that our online algorithm and Du's offline algorithm are both optimal in a strong sense. Finally, we study the empirical performance of our algorithm and the algorithm of Du (which was only theoretically studied previously), and show that they consistently outperform previously suggested algorithms on revenue maximization, location summarization, and quadratic programming applications.

@inproceedings{mualem2023resolving,
  title={Resolving the approximability of offline and online non-monotone dr-submodular maximization over general convex sets},
  author={Mualem, Loay and Feldman, Moran},
  booktitle={International Conference on Artificial Intelligence and Statistics},
  pages={2542--2564},
  year={2023},
  organization={PMLR}
}
Partial monotonicity

Using Partial Monotonicity in Submodular Maximization

Loay Mualem, Moran Feldman

NeurIPS 2022

Over the last two decades, submodular function maximization has been the workhorse of many discrete optimization problems in machine learning applications. Traditionally, the study of submodular functions was based on binary function properties, but recent works began to consider continuous function properties such as the submodularity ratio and the curvature. The monotonicity property of set functions plays a central role in submodular maximization. Nevertheless, no continuous version of this property has been suggested to date (as far as we know), which is unfortunate since submodular functions that are almost monotone often arise in machine learning applications. In this work, we fill this gap by defining the monotonicity ratio, which is a continuous version of the monotonicity property. We then show that for many standard submodular maximization algorithms one can prove new approximation guarantees that depend on the monotonicity ratio; leading to improved approximation ratios for the common machine learning applications of movie recommendation, quadratic programming, image summarization, and ride-share optimization.

@article{mualem2022using,
  title={Using partial monotonicity in submodular maximization},
  author={Mualem, Loay and Feldman, Moran},
  journal={Advances in Neural Information Processing Systems},
  volume={35},
  pages={2723--2736},
  year={2022}
}
Pruning neural networks

Pruning Neural Networks via Coresets and Convex Geometry: Towards No Assumptions

Murad Tukan, Loay Mualem, Alaa Maalouf

NeurIPS 2022

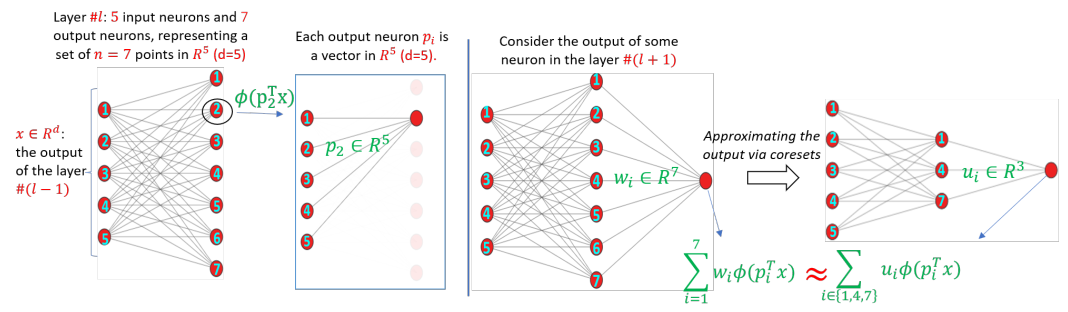
Pruning is one of the predominant approaches for compressing deep neural networks (DNNs). Lately, coresets (provable data summarizations) were leveraged for pruning DNNs, adding the advantage of theoretical guarantees on the trade-off between the compression rate and the approximation error. However, coresets in this domain were either data dependant or generated under restrictive assumptions on both the model's weights and inputs. In real-world scenarios, such assumptions are rarely satisfied, limiting the applicability of coresets. To this end, we suggest a novel and robust framework for computing such coresets under mild assumptions on the model's weights and without any assumption on the training data. The idea is to compute the importance of each neuron in each layer with respect to the output of the following layer. This is achieved by an elegant combination of LΓΆwner ellipsoid and Caratheodory theorem. Our method is simultaneously data-independent, applicable to various networks and datasets (due to the simplified assumptions), and theoretically supported. Experimental results show that our method outperforms existing coreset based neural pruning approaches across a wide range of networks and datasets. For example, our method achieved a 62% compression rate on ResNet50 on ImageNet with 1.09% drop in accuracy.

@article{tukan2022pruning,
  title={Pruning neural networks via coresets and convex geometry: Towards no assumptions},
  author={Tukan, Murad and Mualem, Loay and Maalouf, Alaa},
  journal={Advances in Neural Information Processing Systems},
  volume={35},
  pages={38003--38019},
  year={2022}
}
Online bin packing

Online Bin Packing of Squares and Cubes

Leah Epstein, Loay Mualem

Algorithmica

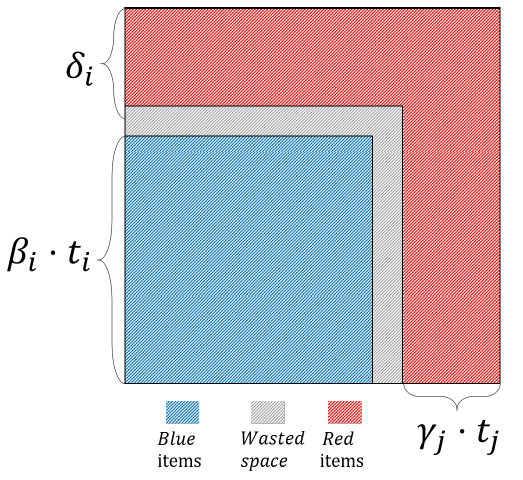
In the d-dimensional online bin packing problem, d-dimensional cubes of positive sizes no larger than 1 are presented one by one to be assigned to positions in d-dimensional unit cube bins. In this work, we provide improved upper bounds on the asymptotic competitive ratio for square and cube bin packing problems, where our bounds do not exceed 2.0885 and 2.5735 for square and cube packing, respectively. To achieve these results, we adapt and improve a previously designed harmonic-type algorithm, and apply a different method for defining weight functions. We detect deficiencies in the state-of-the-art results by providing counter-examples to the current best algorithms and their analysis, where the claimed bounds were 2.1187 for square packing and 2.6161 for cube packing.

@article{epstein2023online,
  title={Online bin packing of squares and cubes},
  author={Epstein, Leah and Mualem, Loay},
  journal={Algorithmica},
  volume={85},
  number={5},
  pages={1415--1458},
  year={2023},
  publisher={Springer}
}